For telehealth · online labs · health apps
Online lab testing that comes back read, not as a PDF.
Direct-to-consumer labs, telehealth services and health apps let people order a lab test online, and what comes back is a PDF. Vitrubo is the interpretation layer the provider adds: every value read against its range and the person's history, a drafted comment for the reviewing clinician and a plain-language report for the customer, under the provider's brand. Vitrubo does not perform or sell lab tests.
- HIPAA compliant
- GDPR compliant
- Encrypted in transit and at rest
- HL7 · FHIR R4
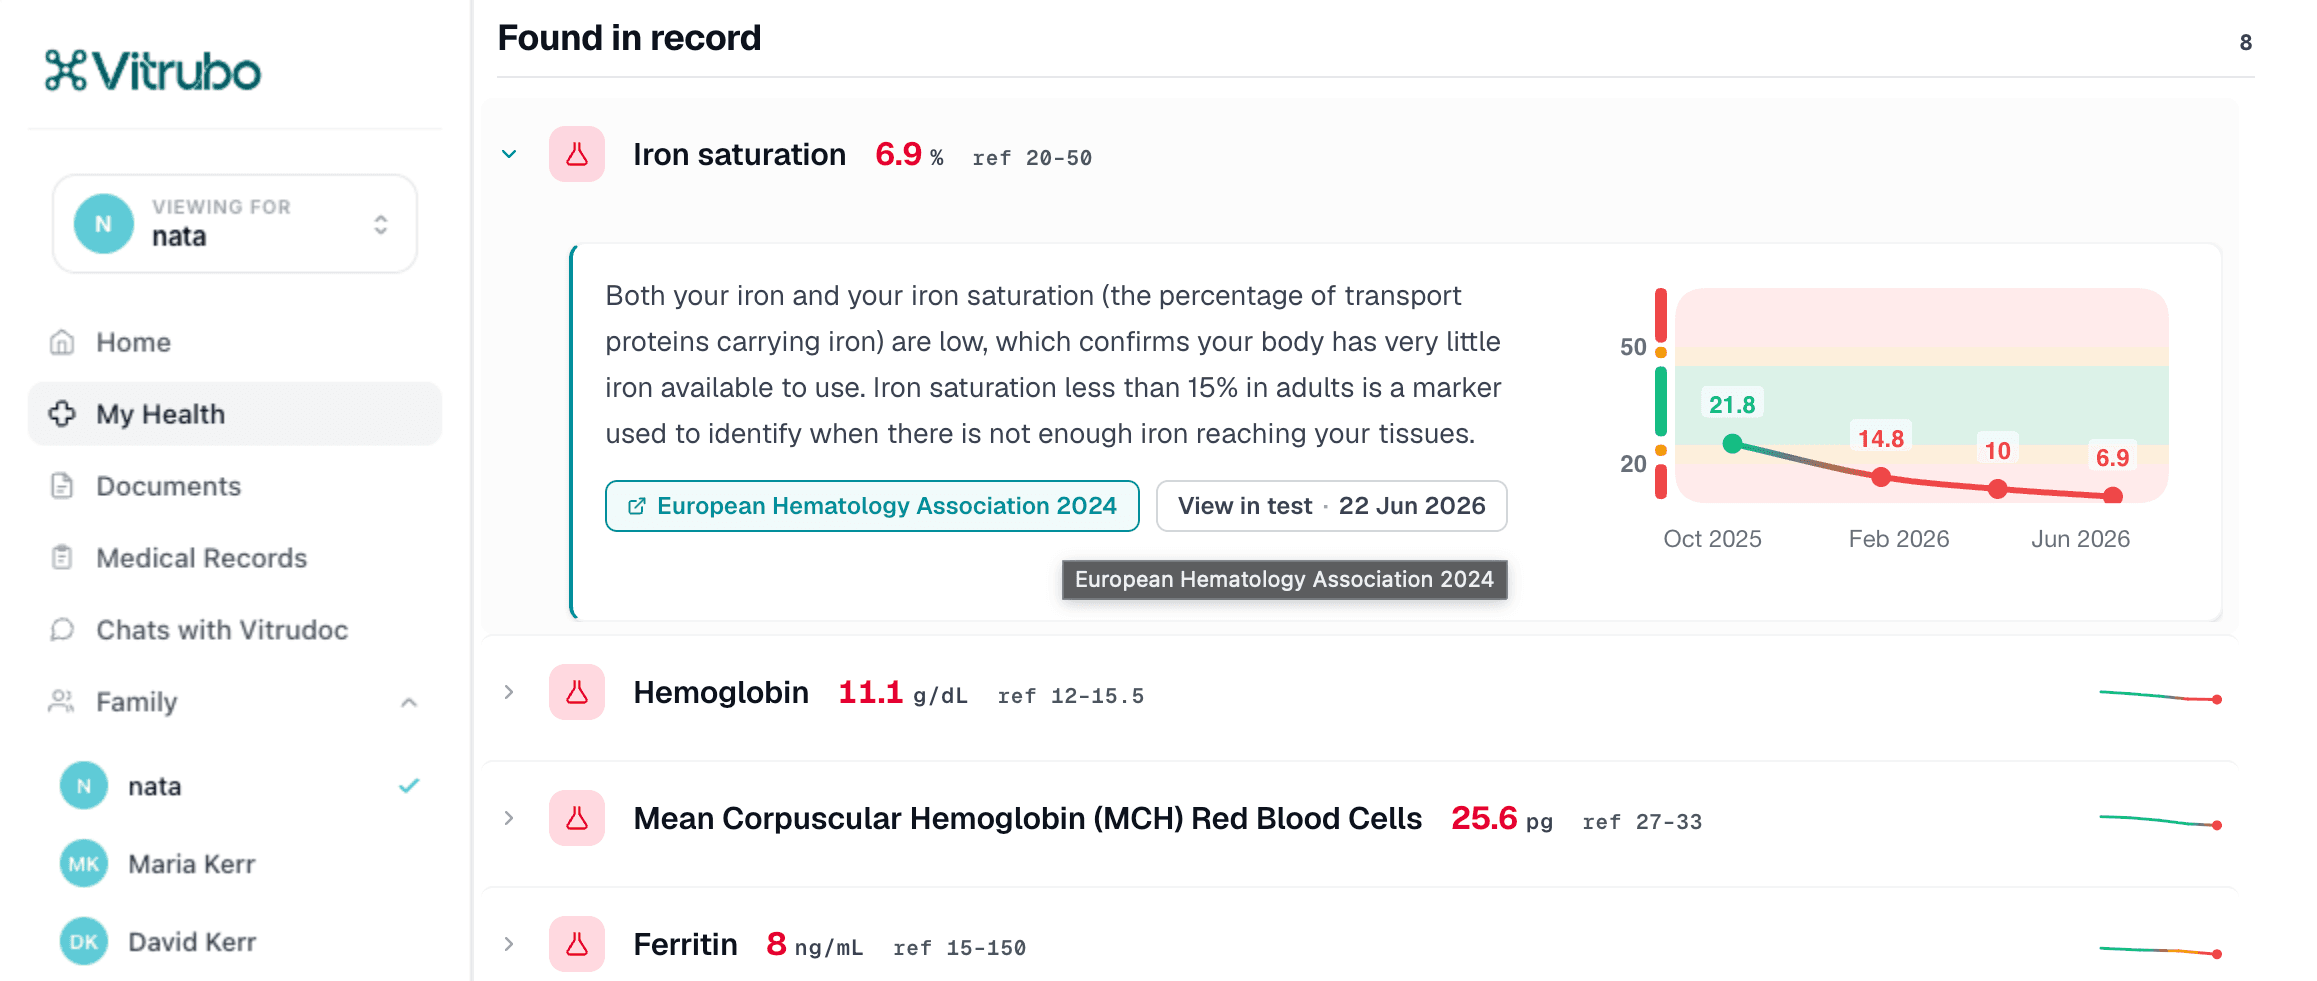
The reading layer behind online lab testing.
LOINC codes
An online lab test may be drawn at any partner laboratory. Every value lands on one reference standard, so a test ordered this year reads against one ordered elsewhere last year.
However the lab reports
Partner laboratories return results as PDF, HL7 or FHIR. All of them are read into one FHIR R4 record; the interpretation comes back as JSON through the API.
Native record
One FHIR R4 record per person, every result coded and dated, the source document kept. HIPAA business associate agreement for US deployments, GDPR Article 28 terms and Standard Contractual Clauses as standard.
Tasks on MedAgentBench
Stanford MedAgentBench, five runs, every task passed. Under it, roughly 100,000 anonymised hospital records read on premises in a clinical program.
Who adds a reading layer to online lab testing?
Several kinds of provider sell a lab test online, and one person orders it. The provider keeps its lab, its brand and its clinician; Vitrubo drafts the reading.
A report the customer understands.
The customer ordered a lab test online and paid for an answer, not a table. Each flagged value comes with what it means, how it moved since the last draw and what to raise with a doctor, in plain words under your brand.
The panel read before the video call.
A lab test online is ordered in the consultation and returns days later. The clinician opens a drafted reading with the reasoning, connected medications and tests to consider, reviews it and signs. The follow-up call starts from the answer.
Every test result brings the user back.
Embed, bundle or resell the interpretation inside your app. Each new test regenerates the report and extends the trend line, so the value of online lab testing accumulates rather than resets.
What Vitrubo does with an online lab test.
A lab test online returns values and reference ranges. Vitrubo reads them together: which markers move as a group, what the medication list changes, what a borderline result means beside two others. Numbers, units, ranges and flags are computed by deterministic code, never written by a model.
People who use online lab testing repeat it: a baseline, a change of habit, a check some months later. Each draw is normalised to one standard, so the same marker reads as one line across laboratories and years, and drift that no single test would show becomes visible.
Online lab tests usually pass a clinician before release. Vitrubo drafts the comment beside every flagged result, with the guidance it rests on; the clinician reviews, edits and signs inside the existing step.
The same analysis in a second view. Flagged results grouped into a few connected stories in four zones: needs attention, worth watching, back to normal, always normal. The customer reads what stands out in their test and what to discuss with a doctor.
Every statement links to the medical guidance it rests on: EHA, WHO, NICE, KDIGO and BSH among the sources. Up to 30 sources stand behind one biomarker view, and a chip opens the publication.
White-label PDFs and a role-based portal carrying your logo and disclaimers, or JSON through the API into your own product. Containers on your infrastructure or a private cloud; you own the keys and Vitrubo has no access to the data.
The whole record, not one lab test.
A person who orders a lab test online usually holds other results too: a hospital letter, a prescription photo, last year's panel from another lab. Vitrubo files them all into one record and reads the new test against it. Hospital records, prescriptions and notes are read as context; blood, urine and allergy panels arrive as values. The clinician sees the connections; the customer sees a report that already knows their history.
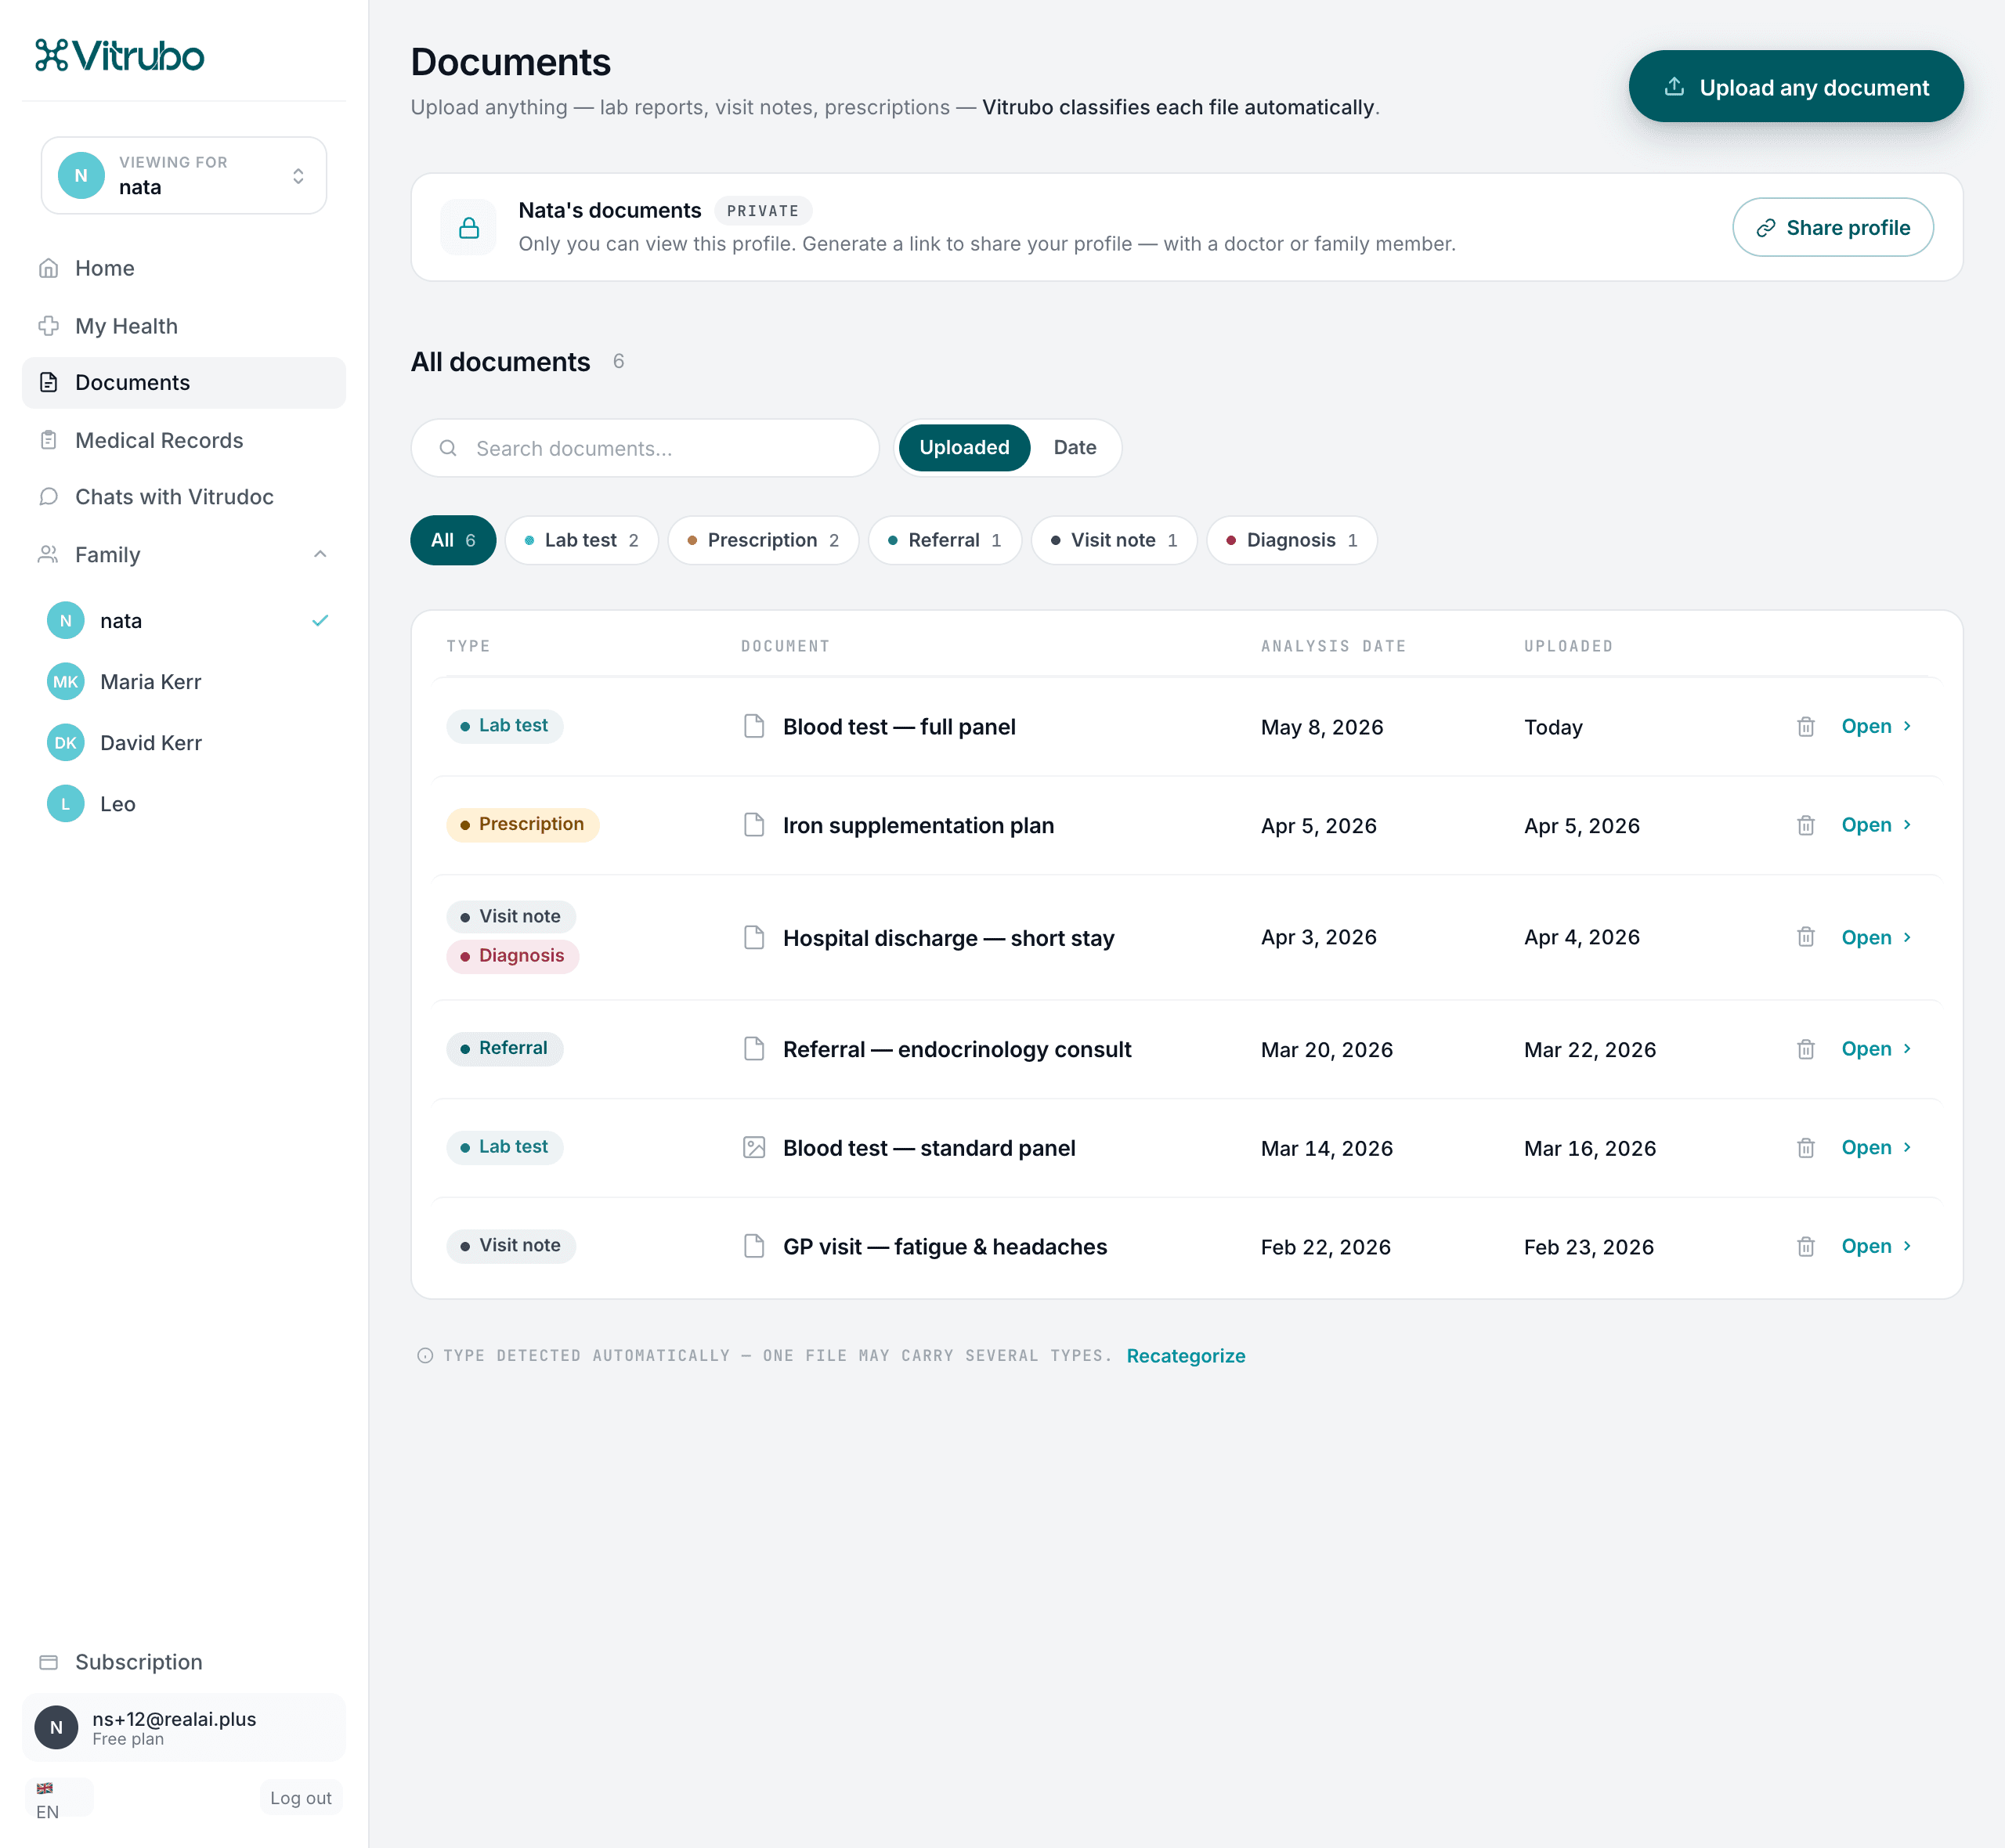
Fits the way online lab testing already runs.
From lab result to reading, automatically.
The partner laboratory releases the result as HL7, FHIR or PDF. Vitrubo reads it, drafts the interpretation and returns it to your portal or the customer's app, with the follow-up test raised from the record rather than by hand.
PlatformPortal, no engineering.
A role-based portal for your clinicians and your customers under your brand. Test results and reports appear there; nothing to build to begin.
API for your own product.
Post the lab result as PDF, HL7 or JSON; receive the structured record, the interpretation and the customer report as JSON. Recognition, normalisation and interpretation, together or one at a time.
One record, whichever lab drew the sample.
Results mapped to LOINC, units made comparable, the record kept in FHIR R4. Tests from every partner laboratory read as one history.
Why not paste the PDF into a chatbot?
Because a lab test result is not a prompt.
A general-purpose model
- Not designed or validated for laboratory results; it writes fluently about a test it may have misread.
- Struggles with a multi-page lab PDF and drops or swaps a number without noticing.
- No normalisation: units and reference ranges differ from one online lab to the next and stay that way.
- Reads each test on its own, so a value drifting across draws goes unremarked.
- No source behind a statement, so nothing a clinician can check before signing.
A reading layer built for lab results
- Lab-native ingestion of PDF, photo, HL7 and FHIR. Numbers are computed by deterministic code, never written by a model.
- A normalisation engine for units, ranges and LOINC mapping, so a lab test from any provider lands on the same scale.
- Several AI models cross-check the same case; disagreements are resolved and omissions caught before a draft is shown.
- Cited claim by claim: every statement links the medical guidance it rests on, and a chip opens the publication.
- Built for the next draw: the report regenerates with each result, previous versions stay as history, and the right re-test is raised with its reason.
Every statement rests on named medical guidance. Each chip opens the same guideline page a clinician would read.
From first call to production, on your own online lab tests.
An evaluation runs on the result formats your partner laboratories actually return. Six steps, none of them a commitment until the last.
Talk to the team
A short call about your test menu, your partner laboratories, their result formats and where the reading should appear in your flow.
Sandbox and API docs
Test access for your team, the API contract and sample payloads for a lab result posted as PDF, HL7 or JSON.
Run your own lab tests
Send real result formats, anonymised. Blood, urine and allergy panels exactly as your partner labs release them.
Validate the output
Your reviewing clinician compares the drafts and the customer reports against their own reading, alone or together with us.
No commitment at this stage
Evaluation is an evaluation. Configuration of comment style, reference ranges, branding and portal roles happens here.
Production when ready
Containers inside your perimeter or a private cloud, connected to the partner lab feed, your portal or your app.
Questions about online lab testing.
No. Vitrubo does not draw blood, run a laboratory or sell a lab test online. It is the interpretation layer a direct-to-consumer lab, telehealth service or health app adds to the results its partner laboratory returns, and the layer a person can use to understand a result they already hold.
Start with the flags: a result outside its reference range is marked, but a single flagged value rarely means much on its own. What matters is the group it belongs to, how it compares with an earlier draw, and which medication or condition might explain it. The live reports on this page show what that reading looks like; if your provider uses Vitrubo, your report is built the same way. A report is context to bring to a doctor, not medical advice.
A plain-language report: flagged results grouped into a few connected stories in four zones, needs attention, worth watching, back to normal and always normal, each with what it means and what to discuss with a doctor. Trends for every marker across previous draws, and the sources behind each statement one tap away. Delivered as a branded PDF, in the portal or inside the provider's app.
The same analysis in the clinician view: full reasoning, connected conditions and medications, tests to consider, and a drafted comment beside every flagged result with the guidance it rests on. The clinician reviews, edits and signs. Vitrubo drafts; it does not decide.
Yes. Every result is mapped to LOINC and its units made comparable, so a lab test online from one partner laboratory and an older hospital panel read on the same line. That is what makes online lab testing useful over time: each later draw is read against the ones before it.
Whatever they already return. PDF, HL7, FHIR R4 or JSON through the API are all read into one FHIR R4 record; a photo of a paper test result is read as well. Blood, urine and allergy panels arrive as values; hospital records, prescriptions and notes are read as context.
A HIPAA business associate agreement for US deployments, a GDPR Article 28 processing agreement and Standard Contractual Clauses. Encryption in transit and at rest, and identity never enters the prompt: the models see values and an internal ID, never a name.
Every statement links to named medical guidance, so the basis for a claim can be checked rather than trusted. Numbers, units, ranges and flags are computed in code; several AI models cross-check the same case before a draft is shown. In a clinical program roughly 100,000 anonymised hospital records were read on premises, and on Stanford MedAgentBench Vitrubo completed 600 of 600 tasks across five runs. The clinician still signs.
No. It does not diagnose, select or recommend treatment, or replace a clinician or laboratory scientist. It drafts a reading, organises the history and names the tests to consider. The decision stays with the professional; for the customer, the report is educational context to bring to an appointment.
Yes. White-label PDFs and a role-based portal carry your logo, headers and disclaimers; or take JSON through the API and render the report in your own product. Comment style, reference ranges and answer style per audience are configured for each deployment.
An AI chat grounded only in the person's own record. A customer who has just received a lab test online can ask what a flagged value means, whether it has moved since the last test and what to ask their doctor; the answers come from their results and the guidance behind them, not from the open web. It is switched on per deployment.
With a call, then sandbox and API access. Your team runs its own anonymised lab tests through the pipeline, your clinician validates the drafts, and nothing is committed at that stage. Production follows when you are ready, inside your perimeter or a private cloud.
Demo cases
Invented people, real product. Every case is a synthetic record with a stock portrait: no real patient, no real result. The reports are live.
Robert Hensley
58A year of CKD follow-up with full context supplied.
Emily Carter
34Five visits over nine months with no diagnosis supplied.
Ryan Hayes
30Fifteen months of lifestyle change. The direction of travel is read.
See it on the tests your customers order online.
A walkthrough on the result formats your partner laboratories return, sandbox access for your team, and a drafted report on your own online lab tests.